DFT vs Machine Learning: Which Fits Chemical R&D?
Your computational chemist has a queue of 400 candidate molecules waiting for a property estimate, and the cluster is already booked for the next two weeks. Meanwhile, the formulation team wants answers by Friday. This is the moment when the DFT vs machine learning question stops being academic. Density functional theory gives you physics you can trust on structures nobody has made yet; machine learning in chemistry gives you answers in milliseconds, but only inside the space it has seen. Choosing wrong costs either months of compute or a model that confidently predicts nonsense. This guide lays out where each approach wins, where each fails, and how most industrial R&D teams end up combining them.
Why the DFT vs Machine Learning Choice Matters for R&D Managers
The decision is rarely about which method is "better." It is about throughput, trust, and the shape of the chemical space you are working in. A process engineer screening solvent alternatives for a known reaction has a very different problem from a materials group designing a new ligand class with no prior data.
DFT solves the electronic structure of a molecule from first principles. It does not need historical data, which is exactly why it is valuable for novel chemistry. The price is compute time: a single geometry optimization on a medium-sized organic molecule can take hours, and transition-state searches or large conjugated systems can take days. If you want background on how the method works and where it is already used in industrial chemistry, the earlier explainer on density functional theory in chemistry covers the fundamentals.
Machine learning takes the opposite route. It learns a mapping from molecular representation to property from examples. Once trained, inference is nearly free, which makes it the natural choice when you need to rank thousands of candidates. The catch is that the model inherits every bias and gap in its training set. Ask it about a structural motif it has never seen, and the prediction can look just as confident as one it has seen a hundred times.
How DFT and Machine Learning Compare on the Metrics That Matter
The table below summarizes the trade-offs most chemical R&D teams encounter when deciding between the two approaches for property prediction.
| Criterion | DFT | Machine Learning |
|---|---|---|
| Training data required | None; derived from physics | Hundreds to tens of thousands of labeled examples |
| Time per molecule | Hours to days depending on size and functional | Milliseconds once trained |
| Behavior on novel scaffolds | Reliable within method limits | Degrades sharply outside training domain |
| Properties covered | Electronic, energetic, spectroscopic, reactivity descriptors | Any measurable target, including formulation outcomes DFT cannot reach |
| Interpretability | Physically grounded (orbitals, charges, energies) | Depends on model; SHAP and feature importance help |
| Infrastructure | HPC cluster or cloud compute, licensed codes | Standard CPU/GPU; no-code platforms available |
| Systematic error | Functional and basis-set dependent; known failure modes (dispersion, charge transfer) | Data-quality dependent; silent on unseen chemistry |
| Best fit | Mechanism studies, new chemistry, label generation | High-throughput screening, formulation and process targets |
Two rows deserve emphasis. First, DFT cannot predict a coating's adhesion after 500 hours of salt spray or a lubricant's viscosity index. Those are system-level, multi-component properties, and only a data-driven model trained on your own batch records can reach them. Second, machine learning has no notion of chemistry it has not been shown. A model trained on aromatic amines will produce a number for a phosphonate, and that number is close to meaningless.
Where DFT Wins in Industrial Chemistry
DFT earns its compute budget in three situations. The first is mechanistic work: understanding why a catalyst deactivates, which intermediate controls selectivity, or whether a proposed side reaction is thermodynamically accessible. No surrogate model can answer these questions on a system it has not seen.
The second is truly novel chemical space. A specialty chemicals team exploring a new class of flame-retardant phosphorus compounds has no historical dataset, and the public literature is thin. DFT lets them compute bond dissociation energies, HOMO-LUMO gaps, and decomposition pathways before ordering a single reagent.
The third, and increasingly the most important, is label generation. When experimental data is scarce, DFT becomes the data factory. A team can compute descriptors for 2,000 virtual candidates over a few weeks of cluster time and then use those descriptors as features or targets for a machine learning model. The physics does the slow work once; the model does the fast work forever after.
Where Machine Learning Wins in Chemical R&D
Machine learning dominates whenever the question is "which of these many options should we test next" rather than "why does this one behave the way it does." Consider an adhesives group with 1,200 historical formulation records, each with resin, tackifier, plasticizer ratios, and measured peel strength. DFT has nothing useful to say about peel strength. A gradient boosting or random forest model trained on those records can rank 10,000 untested ratio combinations in under a minute and flag the 20 most promising for the bench.
The same logic applies to process targets: yield, impurity profiles, particle size distribution from a crystallization, cure time as a function of temperature and catalyst loading. These depend on reactor geometry, mixing, and raw material lot variation, none of which DFT models. For structure-level properties where large public datasets exist, graph-based models have become competitive; the earlier review of graph neural networks for molecular property prediction walks through where they currently stand against classical descriptors.
The limiting factor for machine learning is almost never the algorithm. It is whether the organization has structured, consistent data to train on, and whether the team is honest about the applicability domain.
The Hybrid Workflow Most R&D Teams Converge On
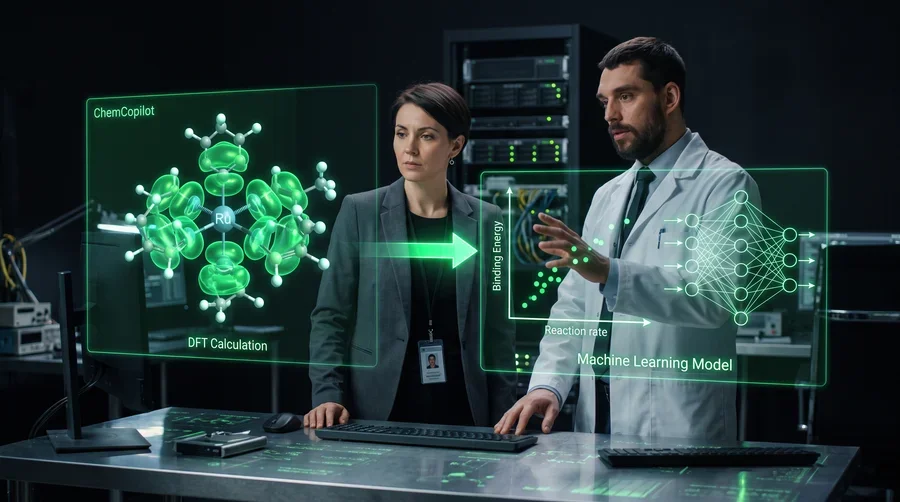
In practice, the DFT vs machine learning debate resolves into a pipeline rather than a verdict. The pattern below shows how a typical materials or specialty chemicals team sequences the two.
Generate 5,000 virtual candidates from building blocks or formulation ranges
Pretrained or in-house model ranks candidates; applicability-domain check flags outliers
Compute electronic descriptors for the top 150 plus flagged out-of-domain structures
DFT outputs become new features and labels; model accuracy improves in the new region
Synthesize or formulate the final 12; results close the loop
A concrete scenario illustrates the payoff. A coatings R&D group evaluating UV absorbers for a new clearcoat started with roughly 3,000 candidate structures from a vendor library. Running DFT on all of them would have consumed the cluster for most of a quarter. Instead, a machine learning model trained on absorbance data from prior projects narrowed the field to 180 structures, with 40 of those flagged as out-of-domain. DFT was run on the 180, taking under two weeks. The DFT-derived excitation energies were fed back as features, and the retrained model reordered the ranking enough that 3 of the final 12 bench candidates would not have made the cut on the first pass. Those 3 included the one that went into the final formulation.
This is also where the tooling matters. Running the loop manually means moving files between a quantum chemistry package, a Python environment, and a spreadsheet. Platforms such as ChemCopilot let R&D teams build the machine learning side of this loop without code, choosing between XGBoost, random forest, neural networks, or Bayesian optimization, and ingest DFT-derived descriptors alongside experimental batch records so the two sources train the same model.
Choosing Between DFT and Machine Learning: A Decision Guide
When a team is unsure which path to take for a given project, a few questions settle it quickly.
Does experimental or computed data already exist for this chemistry? If you have several hundred relevant records, start with machine learning. If you have fewer than 50, DFT is either your primary tool or your label generator.
Is the target property molecular or system-level? Electronic, spectroscopic, and energetic properties are DFT-native. Formulation performance, process yield, and stability are data-native.
How novel is the scaffold or formulation space? If you are extending a known series, a model trained on that series will be reliable. If you are jumping to a new chemotype, treat every ML prediction as a hypothesis until DFT or the bench confirms it.
What is the cost of a wrong answer? A mis-ranked candidate in a 10,000-molecule screen costs almost nothing. A wrong mechanistic conclusion that redirects a two-year catalyst program costs a great deal. Match the rigor of the method to the stakes.
The trap to avoid is treating the choice as permanent. Teams that start with DFT because they lack data should plan from day one to capture those results in a structured format so a model can eventually take over the repetitive work. Teams that start with machine learning should budget DFT time for exactly the cases where the model's uncertainty is highest.
Key Takeaways
DFT and machine learning are not competitors; they occupy different positions in the same workflow. DFT provides physics-grounded answers for new chemistry and mechanistic questions, at the cost of hours to days per structure. Machine learning provides near-instant ranking across thousands of candidates and reaches system-level properties DFT cannot, but only within the domain its data covers. The highest-performing industrial pipelines use ML to narrow, DFT to validate and enrich, and structured data capture to make each cycle faster than the last.
FAQ
Can machine learning replace DFT calculations entirely?
Not for novel chemistry or mechanistic questions. A model has no information about structures outside its training distribution, and no applicability-domain check can create knowledge that is not in the data. ML can replace DFT for repetitive property estimation within a well-sampled chemical series, which is where most of the compute time was being spent anyway.
How much data do I need before machine learning beats DFT on accuracy?
It depends on the property and the diversity of the chemical space, but for a single property within a related series, teams often see useful models with a few hundred well-curated records. For broad, structurally diverse spaces, thousands of examples are usually needed, which is why DFT-generated labels are so commonly used to fill the gap.
What is the difference between DFT and molecular dynamics?
DFT computes the electronic structure of a molecule at fixed nuclear positions and is used for energies, orbitals, charges, and reaction barriers. Molecular dynamics simulates the motion of atoms over time using force fields and is used for conformational sampling, diffusion, and bulk-phase behavior. They answer different questions and are often used together.
Do I need to know Python to use machine learning for property prediction?
No. No-code chemistry AI platforms let formulators and process engineers upload tabular or SMILES-annotated data, select a model type, and run predictions and in-silico sweeps without writing code. Coding is still valuable for custom feature engineering, but it is no longer a prerequisite.
How accurate is DFT for predicting reaction energies?
Accuracy depends heavily on the functional and basis set. Modern hybrid and dispersion-corrected functionals perform well for many organic reactions, but known weaknesses remain for charge-transfer states, strongly correlated systems, and some transition metals. For decisions with high stakes, benchmarking the chosen method against a few experimental anchors is standard practice.
Deciding where DFT ends and machine learning begins is one of the highest-leverage architecture choices an R&D team can make this year. If you want to see how a hybrid property-prediction loop would look on your own data, talk to the ChemCopilot team.