Liberating "Dark" Lab Data: How to Structure 100+ Legacy R&D Projects for AI
Author: Dr. Kyle Fujdala | Chief Science Officer, ChemCopilot
Category: Laboratory Digital Transformation & Data Engineering
Last Updated: September 2026
About the Author: Dr. Kyle Fujdala is the Chief Science Officer at ChemCopilot. He holds a Ph.D. in Chemistry from UC Berkeley and brings over 25 years of industry experience leading materials discovery, active learning frameworks, and commercial R&D teams.
As explored in our foundational analysis on Unlocking Dark Data and Eliminating Dark IT in Chemical R&D, over 55% of physical laboratory intelligence remains unindexed, unsearchable, and functionally invisible across corporate desktops.
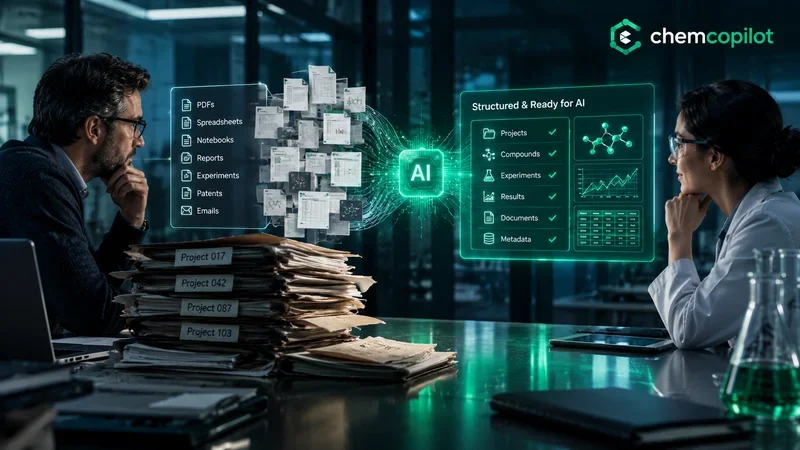
While understanding the strategic risk of Dark IT is essential, R&D directors frequently ask the next operational question: How do we actually transform 100+ historical projects locked in static PDFs, Excel files, and Word reports into clean, row-per-experiment datasets for machine learning?
The answer requires moving away from manual data entry and adopting automated, chemistry-aware data engineering pipelines.
The 4-Column Relational Schema for Chemical Data
To train surrogate models and active learning algorithms, unstructured lab files must be parsed into a standardized 4-column relational table:
3 Steps to Automate Historical Data Ingestion
Step 1: Connecting Analytical and Synthesis Logs via Unique Identifiers
Legacy data often lives in fragments: synthesis parameters are recorded in a Word lab sprint, while analytical HPLC/FTIR assay outputs sit in a LIMS database. By deploying AI chem agents, historical records are automatically linked across file types using unique batch numbers, lot IDs, or sample codes, creating a complete record for every experiment.
Step 2: Extracting "Failed" Experimental Coordinates
In physical chemistry, negative results define the explicit boundary limits where formulations breakdown. Automated data engineering engines parse obscure footnotes and discarded trial logs, converting historic "failures" into high-value coordinates that prevent future project teams from repeating dead-end trials.
Step 3: Forward Deployed Engineering (FDE) Acceleration
To prevent internal IT backlogs from stalling AI initiatives, Forward Deployed Engineering (FDE) teams work directly alongside internal database leads. FDE engineers build custom ETL pipelines, sanitize dark PDF archives, and connect SAP ERP cost feeds behind your corporate firewall—delivering production-ready machine learning models in 4 to 8 weeks.
Automated Schema Structuring with RAG Chem Agents
To eliminate the manual nightmare of combing through thousands of legacy files, ChemCopilot deploys domain-specific Chemcopilot ChemAgents powered by Retrieval-Augmented Generation (RAG). As detailed in our technical breakdown on How Retrieval-Augmented Generation (RAG) Transforms LLMs for Enterprise Chemistry, RAG enables intelligent agents to parse unstructured PDFs, instrument output logs, and legacy notebooks directly behind your secure firewall.
Instead of spending up to 40% of their working hours manually copying values into Excel, scientists rely on Chem Agents to instantly ingest, sanitize, and map dark laboratory data into clean 4-column relational schemas. This automated retrieval layer saves hundreds of lab hours, prevents redundant physical testing, and dramatically accelerates the discovery and launch of next-generation chemical products.
Unlocking Enterprise R&D Velocity
Transforming historical lab intelligence from forgotten desktop spreadsheets into structured, machine-readable datasets is no longer a multi-year IT bottleneck. By combining RAG-powered Chem Agents, chemistry-aware data schemas, and Forward Deployed Engineering, chemical enterprises can liberate decades of dark data behind their sovereign security perimeters. Eliminating Dark IT workarounds not only secures core intellectual property, but also turns historical trial-and-error into an active competitive advantage—accelerating R&D velocity and driving product innovation from day one.
Liberate Your Dark Lab Data with ChemCopilot
Ready to turn years of scattered spreadsheets and LIMS logs into actionable predictive models? Connect with Dr. Kyle Fujdala and our Forward Deployed Engineering team to audit your historical lab data.
Schedule a Private Data Engineering Audit | Subscribe to the Weekly Chemical AI Newsletter