No-Code AutoML for Formulators: Spreadsheets to SMILES Embeddings
No-Code AutoML for Formulators: From Spreadsheet Data to Virtual Sweeps
Last updated: August 20, 2026Formulation development is inherently multi-variable and non-linear. Whether compounding concrete mixtures, formulating personal care skin creams, or engineering controlled-release agricultural granules, scientists must balance raw ingredient proportions, functional category constraints, processing conditions, and multiple competing physical performance targets simultaneously.
Historically, formulators tackled this complexity using classic Statistical Design of Experiments (DOE) software. However, conventional DOE frameworks rely heavily on linear or low-order polynomial assumptions that fail to capture step-function interactions—such as rheology modifier thresholds or phase-inversion boundaries. Conversely, handing raw experimental data over to internal computational data science teams creates frustrating multi-week backlogs. Bench formulators wait for data scientists to manually write Python scripts, clean CSV files, and tune models that often lack wet-lab domain intuition.
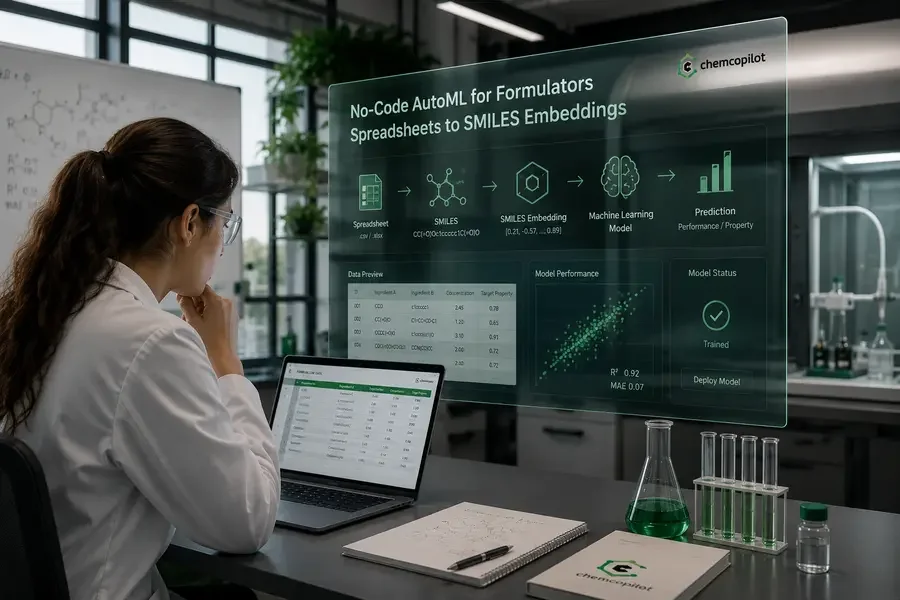
The emergence of specialized No-Code Automated Machine Learning (AutoML) eliminates this friction. By providing point-and-click graphical interfaces directly over standard laboratory spreadsheets, modern platforms allow bench formulators to train advanced neural networks, execute thousands of virtual candidate sweeps, and leverage high-dimensional SMILES chemical embeddings without writing a single line of code.
1. The Data Pipeline: Structuring Spreadsheets for No-Code Ingestion
Before an AutoML engine can fit surrogate response models, historical laboratory datasets must be structured cleanly. Rather than requiring complex database architectures, modern systems ingest standard CSV or Excel files containing organized experimental rows.
Consider an industrial formulation dataset—such as a concrete structural mixture or a topical personal care emulsion. The data schema must capture four core variable types:
- Quantitative Component Amounts: Continuous numerical weight fractions or mass inputs representing raw precursor proportions (e.g., cement mass, water volume, fly ash, slag, or polymer plasticizers).
- Processing & Aging Parameters: Operational variables representing environmental or process conditions, such as curing time (aging days), mixing shear speed, or reaction temperatures.
- Qualitative & Categorical Descriptors: Discrete categorical variables capturing ingredient trade names, batch supplier codes, or binary switches (e.g., process state on/off, or sensory profiles like "sweet", "fruity", or "sour").
- Physical Performance Targets (Outputs): Quantitative characterization metrics measured in the laboratory, such as compressive strength (MPa), water release rates, viscosity (cP), or thermal stability boundaries.
Within the interface, formulators can customize variable selections. If a parameter remains constant throughout an experimental series—such as a fixed mixing temperature—the user can override the feature selection, excluding co-dependent or static variables to prevent artificial model bias.
2. No-Code Model Training & Statistical Diagnostics
Once data is loaded into the platform, model configuration occurs entirely via visual button selections. Users can train individual algorithms or run multi-model comparisons simultaneously, selecting training speeds ranging from rapid validation to deep optimization cycles.
Core Model Architectures in No-Code Formulation AI
- TabPFN (Tabular Prior-Data Fitted Networks): A breakthrough transformer-based tabular foundation model designed specifically to infer complex non-linear relationships across small, sparse datasets (20 to 100 rows) in milliseconds without hyperparameter tuning.
- Deep Neural Networks & k-Nearest Neighbors (k-NN): Non-parametric architectures capable of mapping complex continuous topological spaces across high-dimensional component mixtures.
- Ensemble Regression Models: Tree-based algorithms (such as Random Forests and Gradient Boosting) that excel at handling mixed numerical and categorical input feature sets.
Evaluating Model Validity: Correlation & Feature Importance
Upon completion of training, the platform generates interactive diagnostic plots to evaluate predictive performance:
Diagnostic correlation plots compare predicted values against physical bench measurements, displaying the Coefficient of Determination (R²) and Root Mean Squared Error (RMSE). In real-world lab environments, formulators utilize these metrics for directional guidance. For instance, if an RMSE value indicates an experimental error margin of ±4 MPa on compressive strength, formulations falling within that margin are treated as statistically equivalent, while distinct performance jumps (e.g., Formulation A outperforming Formulation B) provide confident directional paths for physical synthesis.
Concurrently, automated Feature Importance Charts reveal which variables exert the strongest influence over target properties. In a concrete optimization run, for example, the system might reveal that curing aging duration and primary cement volume drive 70% of compressive strength variance, while secondary plasticizer additives exert minimal influence—guiding formulators to focus physical bench trials on the most impactful knobs.
3. Generic vs. Specialized Formulation Modeling
Not all formulation data can be treated identically. Modern AutoML platforms distinguish between Generic Data Modeling and Specialized Formulation Modeling:
| Capability Dimension | Generic Tabular Modeling | Specialized Formulation Modeling |
|---|---|---|
| Trade Name Dependencies | Treated as simple text labels | One-Hot Encoding: Learns non-linear interaction dependencies between specific trade-name combinations. |
| Functional Component Tagging | No functional context | Functional Role Assignment: Assigns explicit roles (e.g., rheology modifier, surfactant, humectant, preservative). |
| Interaction Effect Learning | Assumes independent inputs | Cross-Category Interactions: Learns synergy or antagonism between distinct functional categories (e.g., polymer-clay interactions). |
| Combinatorial DOE Constraints | Unconstrained random space | Category Range Limits: Restricts minor additive categories (e.g., fragrances < 1%) to prevent unviable recipes. |
By tagging components with explicit functional roles (such as surfactants, thickeners, active nutrients, or plasticizers), the specialized formulation engine models cross-category interactions. It learns whether a specific rheology modifier synergizes with a given base surfactant, preventing the system from suggesting chemically unviable combinations during automated trial generation.
4. Virtual Sweeps, Multi-Objective Optimization & AI DOE
Once a validated surrogate model is established, the platform shifts from retrospective analysis to prospective digital experimentation. Formulators can execute three distinct types of virtual experimentation:
A. In-Silico Parameter Sweeps (Sensitivity Analysis)
Formulators select a baseline physical experiment from historical records as a starting candidate. The user defines fixed parameters while sweeping target variables across continuous ranges (e.g., varying a precursor mass from 30 kg to 600 kg across 10 steps). By sweeping multiple variables simultaneously, the system constructs a combinatorial matrix—evaluating 100 to 1,000 virtual experiment outcomes in seconds.
B. Multi-Objective Property Optimization
In real-world R&D, formulators rarely optimize a single output. A target product might require minimizing water release rates while maximizing tensile strength and maintaining a strict Bill of Materials (BOM) cost ceiling. The automated optimizer evaluates thousands of virtual component permutations against user-defined constraints, outputting the non-dominated Pareto front of candidate recipes.
C. AI-Driven Design of Experiments (DOE)
When launching a new project with sparse or zero historical data, the AI DOE engine generates balanced initial experiment sets:
- Random Exploration Strategy: Ideal for zero-starting-data scenarios, generating uniform exploratory candidate grids across defined input bounds.
- Space-Filling Strategy: Used when baseline data exists (e.g., 50 historical rows). The algorithm detects un-tested gaps in high-dimensional formulation space, generating candidate batches specifically designed to maximize informational gain.
5. Structure-Property Modeling via SMILES Embeddings
When formulation components consist of discrete, pure chemical structures, formulators can upgrade from generic component IDs to Molecular Structure-Property Relationship (QSPR) Modeling.
Computers cannot parse 2D chemical drawings directly. To model structural influence, the platform utilizes SMILES (Simplified Molecular-Input Line-Entry System) strings—text representations encoding atomic connectivity and stereochemistry.
The platform ingests SMILES strings and automatically generates high-dimensional Chemical Embeddings (such as Mordred or Morgan topological descriptors). These numerical vectors uniquely quantify molecular weight, polarizability, surface area, and functional group counts.
Automated Isomer Enumeration & Batch Prediction
Integrated molecular drawing and structure-generation tools allow formulators to input a chemical formula (e.g., C₆H₁₄). The system automatically enumerates all structural possibilities (generating all 5 hexane isomers), calculates their chemical embeddings, and passes the generated structures into the predict table to batch-screen boiling points, solubility, or biological activity in seconds.
6. Visualizing High-Dimensional Spaces with Projection Explorer
A major challenge in multi-component formulation is visualization. How does a formulator conceptualize an experimental space defined by 30 continuous raw materials and processing variables simultaneously?
Modern platforms integrate advanced dimensionality-reduction tools, such as the Projection Explorer. Utilizing algorithms like t-SNE (t-Distributed Stochastic Neighbor Embedding) or UMAP (Uniform Manifold Approximation and Projection), the engine compresses high-dimensional formulation recipes into 2D or 3D visual scatter maps:
- Structural & Recipe Clustering: Formulations with similar chemical compositions or functional categories map close together in visual projection space.
- Property Hot-Zone Mapping: By overlaying performance targets (such as high compressive strength or rapid cure speed) as color heatmaps over the spatial projection, formulators can visually identify "sweet spots" in formulation space.
- Gap Identification: Formulators can visually spot unexplored clusters in recipe space, directing future bench trials toward empty coordinates.
7. The Enterprise Impact of No-Code Formulation AI
Deploying no-code AutoML directly into the hands of physical bench formulators transforms industrial R&D economics. By replacing rigid classical DOE and eliminating custom coding bottlenecks, chemical enterprises achieve radical operational efficiencies:
- 70%+ Reduction in Bench Waste: Screening 10,000 candidate recipes virtually ensures that chemists synthesize only high-probability, Pareto-optimal candidates at the physical bench.
- Democratized Machine Learning: Wet-lab scientists build, diagnose, and deploy advanced neural network models without requiring computational data science degrees.
- Compounded Institutional Knowledge: Historical spreadsheets move from static storage into active surrogate models that continuously learn from every newly completed bench trial.
The future of formulation chemistry belongs to organizations that merge physical chemical intuition with automated digital screening. By adopting no-code AutoML architectures, formulation leaders empower their laboratory teams to discover faster, optimize complex multi-objective properties, and deliver next-generation materials to market in record time.