The model said 4,200 cP. The pilot batch came out at 6,100 cP, the line was down for a shift, and the formulator who trusted the number now trusts nothing the model says. Nobody did anything wrong in that story except one thing: the machine learning chemistry model was asked for a number when it should have been asked for a number and an honest statement of how sure it was. A point prediction with no error bar is not a prediction. It is a guess wearing a lab coat.
This guide covers how to put defensible confidence bounds on formulation and process predictions, how to tell when a candidate sits outside what the model has ever seen, and how to turn that information into a decision rule your R&D team will actually follow.
Why a point prediction fails in machine learning chemistry
Chemical R&D datasets are small, unevenly sampled, and full of regions where the lab simply never went. A coatings team with 180 batch records might have 140 of them clustered around two resin systems and the remaining 40 scattered across one-off trials. A model trained on that data will be reasonably accurate inside the cluster and essentially extrapolating everywhere else. The trouble is that a standard regressor produces the same clean decimal in both cases.
Consider two predictions from the same viscosity model. For a candidate that resembles 60 historical batches, the honest output is something like 4,200 cP with a 90% interval of 4,050 to 4,350. For a candidate using a new thickener at a loading the dataset has never contained, the honest output is 4,200 cP with an interval of 2,800 to 6,400. Both have the same center. Only one of them is a number you would release to the pilot plant. Without the interval, the team cannot distinguish the two, so they either over-trust every prediction or, after the first failure, ignore all of them. Neither mode delivers the time savings a formulation AI investment was supposed to produce.
Uncertainty also has a direct link to interpretability. Feature attributions explain why a model predicts a value; prediction intervals explain how much to believe it. The two work together, and if your team is already using SHAP-style attributions, our guide on explainability in chemistry AI with SHAP values and feature importance is the natural companion to this one.
Four ways to put error bars on a chemistry ML model
There is no single "correct" uncertainty method. Each one makes different assumptions, costs different amounts of compute, and behaves differently when data is sparse. The practical question is which one fits the model architecture you already use and the decision you need to make.
Ensemble variance. Train many models on resampled subsets of the data (a Random Forest already does this internally; Gradient Boosting and Neural Networks can be bagged the same way) and read the spread of their predictions. Wide disagreement between ensemble members signals that the data does not constrain the answer well in that region. It is cheap, requires no extra tooling, and is the easiest first step. Its weakness is that all members share the same training distribution, so the ensemble can agree confidently on a wrong answer far outside the data.
Quantile regression. Instead of training a model to predict the mean, train it to predict the 5th and 95th percentiles directly. Gradient Boosting implementations support this with a quantile loss function. The result is an interval that can be asymmetric, which matters in chemistry: a dispersion may have a hard lower bound on particle size but a long tail upward when it flocculates.
Bayesian methods and Gaussian processes. These treat the model parameters themselves as uncertain and produce a full predictive distribution. Gaussian processes in particular give uncertainty that grows naturally with distance from training points, which is exactly the behavior a formulator wants. This is also the engine behind Bayesian Optimization, where the acquisition function explicitly trades off predicted value against uncertainty to choose the next run. The cost is scaling: above a few thousand records, exact Gaussian processes become slow, and the choice of kernel requires some judgment.
Conformal prediction. A newer, model-agnostic wrapper. You hold out a calibration set, measure how far the model's predictions fall from reality on that set, and use those residuals to build intervals with a guaranteed coverage rate. If you ask for 90% intervals, roughly 90% of future measurements will land inside them, regardless of whether the underlying model is XGBoost, Elastic Net, or a neural network. The guarantee is statistical and assumes future samples come from a similar distribution, so it still does not rescue a prediction far outside the training domain, but it is the most honest general-purpose method for teams who do not want to re-architect their models.
| Method | Works with | Strength | Weakness | Best for |
|---|---|---|---|---|
| Ensemble variance | Random Forest, bagged GBM, NN | Free with tree ensembles | Overconfident far from data | First-pass ranking of candidates |
| Quantile regression | Gradient Boosting | Asymmetric intervals | Separate model per quantile | Properties with one-sided failure modes |
| Gaussian process / Bayesian | Small datasets, BO loops | Uncertainty grows with distance | Scales poorly past ~5k rows | Sequential DOE, sparse data |
| Conformal prediction | Any model | Guaranteed coverage | Needs a held-out calibration set | Regulated or sign-off decisions |
| Applicability domain check | Any model (pre-filter) | Catches extrapolation | Not an interval by itself | Every prediction, always |
Applicability domain: the check that comes before the interval
Every interval method above shares a blind spot. If a candidate is far enough from the training data, the model is not interpolating at all, and even a well-calibrated interval can be wrong because the calibration residuals were measured in a region that no longer applies. The applicability domain check answers a prior question: has this model seen anything like this before?
For formulation tables, the check is usually a distance in composition space: how far is the new ingredient vector from its nearest training neighbors, scaled by the spread of the data. For molecular inputs it is often a fingerprint similarity, where a maximum Tanimoto similarity below roughly 0.4 to the nearest training compound is a common warning threshold. For process data it can be as simple as flagging any input variable outside the range the model was trained on, which a surprising number of teams never implement.
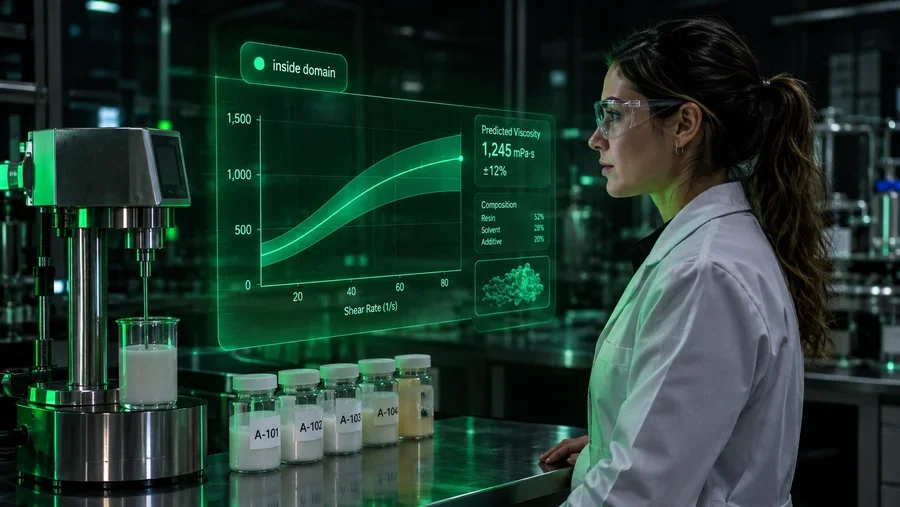
The output of this step is not a number; it is a traffic light. Inside the domain, read the interval and decide. Near the edge, widen the interval mentally and plan a confirmation run. Outside the domain, treat the prediction as a hypothesis, not a forecast, no matter how narrow the computed interval looks.
A decision workflow for uncertainty-aware machine learning chemistry
The value of all this comes from a rule that converts intervals into actions. The workflow below is what mature R&D teams converge on, whether they are predicting viscosity, cure time, emulsion stability, or reaction yield.
Model returns value + 90% interval
Inside / edge / outside training data
Does the whole interval clear the target?
Interval inside spec → proceed
Interval straddles spec → one bench run
Outside domain → treat as DOE point
The key move is step 3. You are not asking whether the predicted value meets the specification. You are asking whether the entire interval does. A candidate predicted at 4,200 cP with an interval of 4,050 to 4,350 against a spec of 4,000 to 4,500 is a release-ready prediction. The same center with an interval of 2,800 to 6,400 straddles the spec on both sides and earns exactly one confirmation batch, not a pilot run.
What this looks like in practice: an adhesives team with 210 records
An industrial adhesives group had 210 historical formulations with measured lap-shear strength, and a new project demanding 36 candidate blends to be screened against a 3.5 MPa minimum. The conventional path was 36 bench preparations and tests, roughly four weeks of a technician's time.
They trained a gradient boosting model with quantile outputs and added a nearest-neighbor domain check on the composition vector. Of the 36 candidates, 19 returned intervals entirely above 3.5 MPa and inside the domain; those went straight to the shortlist. Eight sat below the spec with the entire interval under the line and were dropped without a single preparation. The remaining nine were the interesting ones: five straddled the specification and four used a tackifier loading outside anything in the historical set. Those nine became the physical experiments. Four weeks of bench work became nine runs completed in under one week, and two of the four out-of-domain candidates turned out to be the best performers in the project, which is precisely the kind of discovery a confident-but-wrong point prediction would have screened out.
This is the compounding benefit. The nine runs were not wasted confirmation; they were the most informative experiments the team could have chosen, and once their results were added back to the dataset, the next project's model started with a wider domain. Choosing the next experiment specifically where the model is least certain is the core idea behind active learning, which we cover in depth in how AI chooses the next experiment and why the human guardrail still matters.
Calibration: making sure the error bars are honest
An interval is only useful if its stated confidence matches reality. A model that reports 90% intervals which actually capture the true value 60% of the time is more dangerous than one with no intervals at all, because it invites exactly the over-trust that caused the 6,100 cP batch.
The check is simple and should be routine. Hold out a validation set the model never saw, generate intervals, and count how many measured values fall inside. If you asked for 90% and observe 88 to 92%, the model is calibrated. If you observe 70%, the intervals are too narrow and need widening, which is what conformal methods do automatically. If you observe 99%, the intervals are so wide they will never clear a specification and the model is effectively useless for decisions. Track this coverage number over time; it drifts as new raw material lots, suppliers, and measurement instruments enter the data, and a drop in coverage is often the first sign that the underlying process has shifted.
For teams without a dedicated data scientist, this is where tooling matters. Platforms such as ChemCopilot, built for chemical R&D teams, run these calibration checks and domain flags as part of the no-code modeling workflow across models like XGBoost, Random Forest, and Gaussian-process-driven Bayesian Optimization, so a formulator sees the interval and the domain status next to every prediction without writing a line of Python. The analytical method is the same one described above; the difference is whether a chemist can act on it in the afternoon or has to wait for a modeling request to clear the queue.
Key takeaways
Uncertainty quantification is not a statistical refinement; it is the mechanism that converts machine learning chemistry from a curiosity into a decision tool. Three practices cover most of the value. Report an interval with every prediction and choose the method that matches your model and data size. Run an applicability domain check before you read the interval, because extrapolation defeats every interval method. And verify calibration on held-out data so that a 90% interval really means 90%. Once those are in place, the decision rule becomes mechanical: trust when the whole interval clears spec, verify with one run when it straddles, and treat out-of-domain candidates as the most valuable experiments you can run.
Frequently asked questions
What is the difference between prediction uncertainty and model accuracy?
Accuracy is a global measure of how close predictions are to measured values across a test set, typically reported as RMSE or R². Uncertainty is a local measure attached to a single prediction, describing how confident the model is for that specific candidate. A model can have excellent global accuracy and still be highly uncertain about a particular new formulation that sits far from its training data.
Which uncertainty method should a formulator start with?
For tabular formulation data under a few thousand rows, start with ensemble variance from a Random Forest or bagged Gradient Boosting, combined with a simple range check on every input variable. Add conformal calibration once predictions are being used for sign-off decisions. Move to Gaussian processes when the goal shifts to sequential experiment selection through Bayesian Optimization.
Can uncertainty quantification be done without coding?
Yes. The underlying methods are standard, and no-code chemistry ML platforms expose prediction intervals, domain flags, and coverage checks as part of the model output. The scientific judgment that remains with the chemist is setting the confidence level, the specification limits, and the domain threshold appropriate to the property being predicted.
How wide should a prediction interval be before I stop trusting the model?
Compare the interval width to the specification window, not to an abstract threshold. If the interval is narrower than the spec window and sits inside it, the prediction is actionable. If the interval is wider than the spec window, the model is telling you it cannot resolve the decision and a physical measurement is required. That is useful information, not a model failure.
Does uncertainty quantification help with regulatory documentation?
It helps indirectly. Predicted properties used to support a compliance decision are far more defensible when accompanied by a calibrated interval and an explicit domain statement, because they show the prediction was made within the validated scope of the model. This mirrors the applicability domain requirements that regulators already expect for QSAR submissions.
Ready to see prediction intervals and domain checks on your own formulation data? Talk to the ChemCopilot team and bring a dataset you already have.